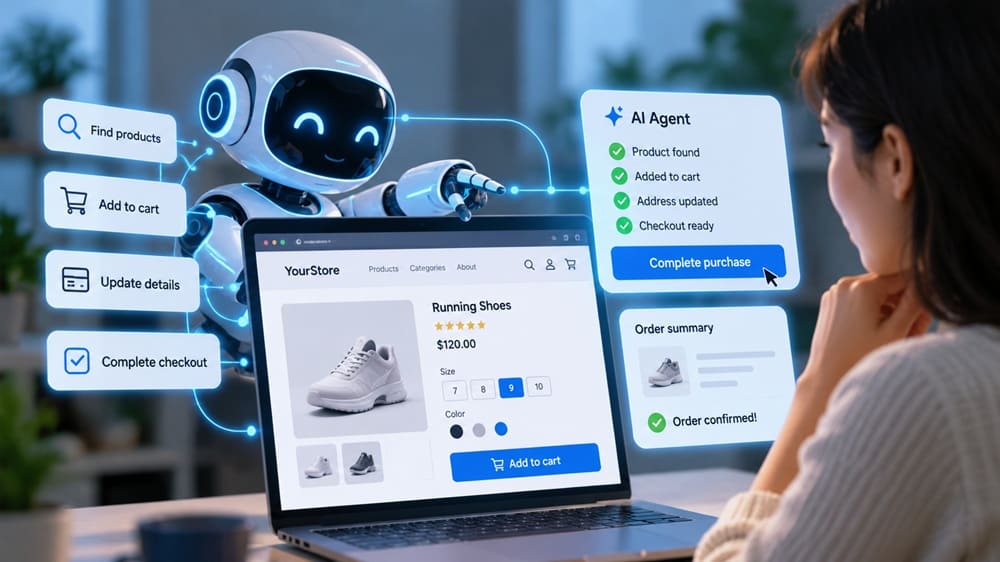
The Agent-Ready Website: What Changes When AI Agents Start Using Websites for Users
Websites were built around a human operating the interface. A visitor reads the page, compares information, chooses an option, fills in a form, and receives a visual confirmation when the task is complete. That operating model is becoming less exclusive. AI agents can already search for information, interpret product and service details, interact with forms, manage shopping carts, and perform parts of a transaction on a user’s behalf.
The change is no longer theoretical. On September 28, 2026, Shopify added WebMCP support for checkout, allowing browser agents to read and update checkout information and submit a purchase after buyer confirmation. Shopify’s existing storefront and cart tools mean an agent can now participate across much more of the shopping process rather than simply reading a product page.
For website owners and developers, that introduces a different engineering problem. The question is no longer only whether a page can be found and understood by search systems. A website increasingly needs to make its information, actions, permissions, and resulting state clear enough for software to use without taking control away from the person it is assisting.
SEO Still Matters, But It Is Not the Whole Problem
It would be a mistake to treat agent-ready development as a replacement for SEO.
Google’s current guidance for AI Overviews and AI Mode says the existing foundations of SEO remain relevant. Google does not require special AI markup or a separate machine-readable file for a page to be eligible for those search experiences; crawlability, internal linking, textual content, page experience, and accurate structured data remain important.
The difference appears when the task moves from finding information to completing an action. A search system may need to determine what a product is, whether a page is relevant, and what information supports the answer. An agent asked to purchase that product has additional requirements. It needs to identify the correct product and variant, understand available actions, provide the right inputs, preserve the transaction state, and determine whether the purchase was actually completed.
A website can therefore be technically healthy for search while still being difficult for an agent to operate. For example, consider an appointment-booking website. A human user can choose a service, select a time from a visual calendar, enter contact details, submit the form, and recognize the confirmation message. An agent-ready workflow needs those same steps to be explicit: the available services and time slots must be identifiable, required inputs must be clearly defined, the booking action must produce a predictable result, and the system must indicate whether the appointment was confirmed, is pending, or failed.
That distinction becomes easier to understand when separating the two requirements:
- Search accessibility: Can systems discover, crawl, interpret, and retrieve the website’s information?
- Agent usability: Can software identify an appropriate action, provide the necessary inputs, and determine what happened afterward?
- Operational control: Can the website restrict what the agent is allowed to read or change?
Traditional SEO addresses much of the first requirement. Agent-ready architecture extends the second and third.
AI Visibility Is Not the Same as Agent Readiness
AI visibility and agent readiness are related, but they solve different problems. AI visibility focuses on whether AI systems can discover, understand, and surface information from a website. Agent readiness focuses on whether software can use that information to interact with the website and complete a permitted task.
The distinction becomes clearer when separating the two requirements:
- AI visibility: Can AI systems understand and retrieve the website’s information?
- Agent readiness: Can an AI agent identify the appropriate action, provide the required inputs, and determine what happened after the action?
Consider a service website that clearly explains its consultation options, pricing, availability, and location. An AI system may be able to use that information to answer a user’s question about the service. An agent asked to book an appointment has additional requirements.
It needs to:
- Identify the service: Determine which consultation the user wants.
- Check availability: Retrieve valid appointment dates and times.
- Provide inputs: Submit the required customer and booking information.
- Execute the action: Complete the booking within its permitted scope.
- Verify the outcome: Determine whether the appointment was confirmed, is still pending, or failed.
This creates an important difference between being understandable to AI and being operable by AI. The two areas still share several foundations. Clear textual content, consistent terminology, accurate structured data, semantic markup, and well-defined information can help AI systems interpret a website. Agent readiness extends those foundations into the website’s interactive and transactional layers.
For website teams, the practical question therefore changes from:
“Can AI understand this website?” to:
“Can authorized software safely use its information and perform its important actions?”
That distinction becomes particularly important when websites move from presenting information to supporting bookings, purchases, enquiries, account changes, and other user tasks.
Pages Need Clearer Meaning
Human users are remarkably good at filling in gaps. A customer can look at a service page, infer that a blue button opens an appointment form, understand which field expects a company name, and recognize that a confirmation message means the request was accepted.
Software has less room for inference when it is responsible for performing the task correctly.
This makes semantic HTML, consistent naming, accessible labels, visible textual information, and accurate structured data more important at the implementation level. Google already recommends that important content be available in textual form and that structured data accurately reflect what users can see on the page. The goal is not to add unnecessary markup to every element. It is to remove ambiguity from the parts of the website that carry business meaning.
For example, a product page should make the following information easy to identify:
- Product name, model, and variant
- Price, currency, and current availability
- Delivery or service conditions
- Relevant policies and restrictions
- Actions available to the user
A service website has a similar requirement. A consultation page should distinguish its description from the scheduling process, identify required information, and make the confirmation state unambiguous. A clearer interface helps humans too. Agent compatibility is therefore often an extension of good information architecture rather than a completely separate discipline.
Important Actions Need Defined Interfaces
The larger architectural change comes when an agent has to operate rather than simply read a page.
Chrome’s WebMCP project is designed around this problem. WebMCP is a proposed web standard for exposing structured tools to AI agents, including through JavaScript and annotated HTML forms. Its declarative API, updated in September 2026, can turn a standard HTML form into a structured tool by defining its name, description, and input fields.
This matters because agents should not have to discover every business action by imitating a human mouse click. A reservation form, for example, may require a date, location, party size, and contact details. A structured interface can define those inputs explicitly, reducing the need for an agent to infer what each field means from surrounding page content.
Chrome’s WebMCP guidance recommends clear tool descriptions, semantic HTML, defined input schemas, reliable outputs, and testing. That is closer to API design than to traditional page optimization. When reviewing important website actions, developers should look for:
- Explicit inputs: Required values should be identifiable without relying on visual placement.
- Clear constraints: Valid ranges, formats, and available choices should be defined.
- Predictable outputs: The system should return a meaningful result rather than forcing the agent to infer success from a page change.
- Recoverable failures: Invalid or incomplete requests should return enough information for the next step to be understood.
Not every website needs WebMCP immediately. Chrome currently describes it as a proposed standard and notes limitations around browser support, tool discovery, and complex interfaces.
The broader lesson is already useful: important website actions should have explicit, predictable interfaces whether those interfaces are delivered through WebMCP, conventional APIs, forms, or another implementation.
Successful Actions Need Verifiable State
An agent cannot reliably complete a task simply by sending an instruction; it also needs to know what happened afterward.
That requirement becomes obvious in commerce. An order may be submitted successfully, rejected by a payment provider, held for additional verification, or accepted with a different delivery estimate. A human can often resolve such situations by reading the interface. An agent needs a structured and unambiguous representation of the resulting state. Google’s Universal Commerce Protocol reflects this direction by providing standardized operations for areas such as identity linking, cart building, checkout, and order management. Its documentation also addresses booking, order status, and related machine-to-machine interactions across supported experiences.
The principle applies beyond ecommerce.
A lead form should return a meaningful status rather than merely changing the page. A support workflow should distinguish between “request received,” “information required,” “escalated,” and “resolved.” An appointment system should make the confirmed time and booking reference available in a form that software can reliably interpret.
For critical workflows, teams should therefore define:
- Successful completion: What exact state confirms that the task is finished?
- Pending state: What tells the agent that the system is still processing the request?
- Failure state: What information explains why the requested operation did not complete?
- Next action: What should happen when additional user input or human intervention is required?
This is an important distinction between a website that contains actions and one that can support reliable task completion.
| Website layer | Human-oriented implementation | Agent-ready consideration |
| Information | Text, images, navigation | Clear entities, fields, relationships, and current values |
| Actions | Buttons, menus, forms | Explicit operations with defined inputs |
| State | Visual confirmation | Structured success, pending, and failure states |
| Access | User login and session | Scoped authorization and permission checks |
| Measurement | Traffic and conversion | Task completion, failure, and handoff monitoring |
The underlying website architecture may remain familiar. What changes is the level of precision expected from each layer.
Authentication Becomes Part of the Interface
Giving an agent the ability to operate a website also creates a permissions problem. An authenticated user may have access to invoices, account settings, personal information, or payment details. That does not mean an agent should be allowed to perform every available action without additional controls.
Chrome’s security guidance for WebMCP specifically addresses the risks of agents operating within authenticated browser sessions. It warns about malicious instructions embedded in tool definitions and contaminated outputs from third-party content, and recommends signals such as readOnlyHint, consequentialHint, and untrustedContentHint to distinguish lower-risk operations from actions that require greater scrutiny.
That creates a useful engineering distinction between access and authority.
A website can allow an agent to retrieve an order status while requiring confirmation before cancelling an order. It can allow an agent to read account information while requiring a separate authorization step before changing billing details. For sensitive workflows, the control model should account for:
- Read-only versus state-changing permissions
- User confirmation for consequential operations
- Scoped and time-limited authorization
- Separation of financial and account-management privileges
- Logging of agent-initiated actions
- Clear human escalation paths
The same principle applies to payments, account deletion, permission changes, and other irreversible operations. Security therefore cannot be added after the agent interface is designed. The permissions model has to be part of the action model from the beginning.
Websites Will Need to Measure Agent Tasks Differently
Traditional analytics tell a business who visited, which pages were viewed, where users dropped out, and which sessions converted. Agent interactions produce different failure points.
An agent can find the correct product but select the wrong variant. It can understand the requested service but fail to submit the form because an input was ambiguous. It can complete an operation but receive an unclear confirmation and remain uncertain about whether the task succeeded. Those failures can disappear inside conventional page analytics.
The tooling emerging around WebMCP already reflects the need for more precise testing. Chrome DevTools can inspect WebMCP tools, invoke them, and examine their inputs, outputs, and errors during development.
For sites supporting agent-operated workflows, teams may eventually need to monitor:
- Task-completion rate
- Tool or API invocation failures
- Authentication and authorization failures
- Human handoff rate
- Repeated attempts
- Average actions required to finish a task
- Percentage of tasks ending with a verifiable outcome
The important metric is not whether an agent visited the site. It is whether the site allowed the agent to complete the intended task accurately and safely.
The Web Is Starting to Expose Capabilities, Not Just Content
The scale of the change remains uncertain, and adoption is still early. Cloudflare’s 2026 analysis of 200,000 of the most visited domains found established mechanisms such as robots.txt to be widespread, while newer agent-oriented mechanisms remained extremely rare. The company found MCP Server Cards and API Catalogs on fewer than 15 sites in that dataset.
That is not evidence that every website needs to implement every emerging standard immediately. It shows that the technical conventions for software-operated websites are still being established.
This matters for developers because infrastructure decisions made now can either preserve flexibility or create another layer of technical debt later. A site that separates business logic from presentation, exposes clean APIs, maintains accurate structured data, uses semantic markup, and treats authorization as a first-class concern has more options as agent interfaces mature.
A site whose important actions depend entirely on visual inference, undocumented state changes, brittle client-side behavior, or broad session permissions will have more work to do.
What Website Teams Should Test Now
The first step is not adding an agent-specific feature for its own sake. It is reviewing the site’s most important user tasks and asking whether their requirements are explicit at the machine level.
For each critical workflow, a team should be able to answer four practical questions.
Can the agent find the required information?
Important facts should be available in clear text, with accurate relationships between products, services, prices, policies, accounts, and other entities.
Can the agent identify the correct action?
Forms, buttons, APIs, and tools should expose clear names, inputs, constraints, and outputs.
Can the agent determine the result?
Success, failure, pending status, and required follow-up should be represented clearly enough for software to act on them.
Can the site limit what the agent is allowed to do?
Read access, state-changing operations, sensitive actions, and user confirmation should have deliberately different permission requirements.
A practical review can also examine the website through five implementation areas:
- Content: Are important facts present in text and consistently named?
- Interaction: Are high-value actions explicit and predictable?
- State: Can software identify what happened after an action?
- Security: Are permissions narrow enough for the task being performed?
- Observability: Can the development team identify where an agent workflow failed?
These checks can be performed without redesigning an entire website.
They also make the concept of agent readiness more concrete. Instead of asking whether a site has “AI features,” a development team can evaluate whether its core customer journeys remain understandable and controllable when software performs part of the work.
The Website Is Becoming an Operating Surface
Markntel Advisor projects the AI agent market to grow from $10.9 billion in 2026 to $110.5 billion by 2032. This growth highlights the need for websites to support secure, reliable agent-driven tasks.
The more useful question for website teams is not whether they should “prepare for AI” in the abstract.
It is whether their most important digital workflows are sufficiently clear, structured, secure, and observable for another software system to operate them reliably on behalf of a user. Search engines made websites compete for discoverability. Agent-based systems introduce another requirement: the site must also make its information and capabilities usable by software without creating uncertainty about permissions or outcomes.
The next generation of websites will still need good content, accessible interfaces, fast performance, and strong search foundations. They will also need to expose their important information and actions with enough precision that both people and software can use them safely.
The shift is not from websites to AI. It is from websites that primarily display information to websites that can support reliable tasks.
Sources/References:
- Shopify — WebMCP support for checkout
https://shopify.dev/changelog/posts/webmcp-support-for-checkout - Chrome for Developers — WebMCP
https://developer.chrome.com/docs/ai/webmcp - Chrome for Developers — WebMCP Declarative API
https://developer.chrome.com/docs/ai/webmcp/declarative-api - Chrome for Developers — WebMCP Best Practices
https://developer.chrome.com/docs/ai/webmcp/best-practices - Chrome for Developers — Agent Security Considerations for WebMCP
https://developer.chrome.com/docs/agents/security - Chrome DevTools — Debug WebMCP Tools
https://developer.chrome.com/docs/devtools/application/webmcp - Universal Commerce Protocol — Official Specification
https://ucp.dev/specification/overview - Cloudflare — Introducing the Agent Readiness Score
https://blog.cloudflare.com/agent-readiness - Google Search Central — AI Features and Your Website
https://developers.google.com/search/docs/appearance/ai-features - Google Search Central — Optimizing for Generative AI Features on Google Search
https://developers.google.com/search/docs/fundamentals/ai-optimization-guide - Markntel Advisor — AI Agent Market Research Report
https://www.marknteladvisors.com/research-library/ai-agent-market.html - Universal Commerce Protocol — Lodging Booking Capability
https://ucp.dev/draft/specification/lodging/booking
